WEEK OF SEP 13 – 19, 2025

R1 passed peer review at $294,000 the same week MCP got a registry and a weaponized proof-of-concept

DeepSeek's R1 becomes the first peer-reviewed mainstream LLM at a disclosed $294,000 training cost, OpenAI ships GPT-5-Codex, GitHub launches the MCP Registry while Kaspersky weaponizes the same protocol, and Beijing shuts Nvidia out of China.

Five dated events carry this week. On Monday OpenAI put a purpose-built agentic coding model behind Codex. On Tuesday GitHub opened a curated registry for MCP servers. On Wednesday Nature published the peer-reviewed DeepSeek-R1 paper with its $294,000 training bill, and Beijing told Alibaba and ByteDance to stop buying Nvidia's China-only accelerator. Codex's dynamic thinking budget, the 74.5% SWE-bench Verified figure and the 512-H800 arithmetic are the numbers that will get quoted at you; the rest is contract and license detail.

The agent toolchain's plumbing got standardized and attacked in the same 24 hours. Kaspersky published a proof-of-concept on Monday in which a rogue MCP server, connected through Cursor, exfiltrated browser passwords, card data, wallet files and cloud configs while showing the victim only legitimate output. The next day GitHub launched the registry meant to make MCP server discovery trustworthy. Neither event is a coincidence of the calendar; they are the same problem — who vouches for the code your agent runs — approached from opposite ends.

Cost is the week's other through-line. DeepSeek's own numbers put the R1 reinforcement-learning phase at $294,000 on 512 H800s for roughly 80 hours, against the much more than $100 million Sam Altman attached to foundation-model training in 2023. Open weights plus a published RL recipe plus a peer-reviewed methods section is a materially different starting position for anyone deciding between per-token contracts and self-hosting.

WED · Sep 17, 2025nvidiachinaexport controlschipsregulation

Beijing orders Alibaba and ByteDance to stop buying Nvidia's China-only accelerator

China's Cyberspace Administration told major domestic technology companies, including Alibaba and ByteDance, to halt testing and cancel existing orders for Nvidia's RTX Pro 6000D, the server chip Nvidia introduced for the Chinese market after US export controls. The Financial Times reported it on 17 September, with Bloomberg, CNBC, TechCrunch and Al Jazeera carrying it the same day. Before the order, several companies had said they would order tens of thousands of units and had already started testing with Nvidia's server suppliers. Beijing's reported conclusion is that domestic accelerators now perform on par with the Nvidia chips export controls still permit into China.

Nvidia shares fell about 3% intraday on the report. Asked about it during Trump's state visit to London, Jensen Huang said he was disappointed and that we can only be in service of a market if a country wants us to be. The order extends guidance from August that targeted the earlier H20, and follows China's accusation that Nvidia violated its antimonopoly law over that same chip.

Beijing orders Alibaba and ByteDance to stop buying Nvidia's China-only accelerator
TechCrunch

WHY IT MATTERS

If you route traffic to Chinese open-weight models through hosted endpoints, the silicon under those endpoints is now explicitly a domestic stack, so throughput, quantization options and price curves will diverge from the Nvidia roadmap you plan against. Plan for your inference supply chain to be two supply chains, and check that the weights and licenses you depend on are matched by serving infrastructure you can actually name.
WED · Sep 17, 2025open weightsdeepseekreasoningreinforcement learningcost

DeepSeek-R1 becomes the first mainstream LLM to pass peer review, and discloses a $294,000 training bill

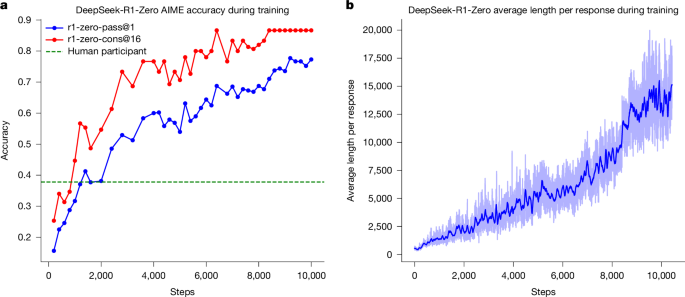
Nature published DeepSeek-R1 incentivizes reasoning in LLMs through reinforcement learning on 17 September 2025, the peer-reviewed successor to January's preprint, with founder Liang Wenfeng listed as a co-author. The supplementary material discloses for the first time what the reasoning phase cost: about $294,000, run on a 512-chip cluster of Nvidia H800s for roughly 80 hours. The authors also acknowledge, for the first time, that they own A100s, used only to prepare experiments on a smaller model beforehand. R1-Zero was trained with pure reinforcement learning and no supervised fine-tuning, rewarded only on final-answer correctness; the paper reports 77.9% pass@1 on AIME 2024.

The paper went through three rounds of review by eight referees who produced 64 pages of reports and responses before a 17 September publication in Nature 645, 633-638. DeepSeek stated in those referee exchanges that R1 was not trained on outputs from OpenAI models, answering the January accusation directly. Nature's accompanying editorial used the occasion to press the rest of the industry, observing that almost no mainstream large model had been independently reviewed.

DeepSeek-R1 becomes the first mainstream LLM to pass peer review, and discloses a $294,000 training bill
media.springernature.com

WHY IT MATTERS

An open-weight reasoning model now has a peer-reviewed methods section, a disclosed compute budget and a reproducible RL recipe — the three things you need before you can justify fine-tuning on top of it instead of renting a closed endpoint. For a team weighing self-hosting against per-token contracts, the $294,000 RL phase plus the base model is the first hard number a vendor has put on frontier-adjacent reasoning, and it sets the reference point against which every closed per-token price gets argued.

TUE · Sep 16, 2025mcpagent infrastructuregithubsupply chain

GitHub opens the MCP Registry, making agent tool discovery a curated directory

GitHub launched the MCP Registry on 16 September as a curated directory of Model Context Protocol servers, each backed by its GitHub repository, with one-click installation inside VS Code and servers surfaced by stars and community activity. Any MCP-compatible host is supported, not just Copilot. Launch partners include Figma's Dev Mode server, HashiCorp's Terraform server and Dynatrace, and the Remote GitHub MCP Server is included. It builds on the MCP project's own registry preview at registry.modelcontextprotocol.io, announced 8 September as an open catalogue and API.

GitHub says it is working with Anthropic and the MCP Steering Committee on an open-source registry that integrates with its own, with self-publication by server authors as the eventual goal. The changelog is explicit that fragmentation is the problem and that a fractured environment fraught with potential security risks is what the registry is meant to close. Twenty-four hours earlier, Kaspersky had shown those risks from the attacker's side.

WHY IT MATTERS

Discovery was the missing dependency-resolution layer for agents: without a canonical index you cannot pin, audit or diff the tools your agent calls. A registry backed by repositories gives you provenance to check before install, and one-click IDE installation removes the last excuse for installing an MCP server you have not read — which is exactly the habit Kaspersky's proof-of-concept punishes.

MON · Sep 15, 2025mcpsecuritysupply chaincursoragents

Kaspersky shows a rogue MCP server draining credentials from a Cursor workstation

Kaspersky's Global Emergency Response Team published a proof-of-concept on 15 September in which a rogue MCP server installed on a developer workstation, connected through Cursor, harvested browser passwords, credit card data, cryptocurrency wallet files, API tokens and certificates, and cloud configurations. The victim sees only the legitimate output of the tool. Kaspersky is explicit that it has not observed the vector in the wild, that this was a controlled lab simulation, and that Cursor and Anthropic were notified of the findings.

The attack does not need a CVE. It exploits the trust model around MCP servers: hidden instructions inside tool descriptions that the model reads but the user does not, server names chosen to be nearly identical to legitimate ones, and tool-definition shadowing in multi-server setups that silently redirects later calls. Kaspersky's mitigations are conventional supply-chain hygiene — scan and approve every server before production, keep an allow-list, and log every prompt and tool call so unexpected SQL, outbound traffic or tool invocations surface in the transcript.

WHY IT MATTERS

An MCP server is a local process your editor launches with your shell, your filesystem and your environment variables, which means every server you install is code you are executing with your credentials — the credential-stealer payload is the tool, not a bug in it. Concretely: run MCP servers in containers, pin them by commit rather than by name, keep the allow-list server-side, and ship the prompt and tool-call log somewhere your agent cannot edit it.

MON · Sep 15, 2025openaicodexagentic codingevalsagent harness

OpenAI ships GPT-5-Codex, a coding model that decides its own thinking budget mid-task

On 15 September OpenAI released GPT-5-Codex, a version of GPT-5 further trained with reinforcement learning on real-world software engineering work, as the default for Codex cloud tasks and code review and selectable in Codex CLI and the IDE extension. OpenAI reports 74.5% on SWE-bench Verified, refactoring performance at 51.3% against 33.9% for GPT-5, and 93.7% fewer tokens than GPT-5 on lightweight interactions. There is no router under the hood: the model reallocates its own reasoning time during a task rather than fixing a budget at the outset, and Codex product lead Alexander Embiricos said he has seen it work more than seven hours on a large job.

It rolled out to ChatGPT Plus, Pro, Business, Edu and Enterprise users across terminal, IDE, GitHub, web and the ChatGPT mobile app, with Codex generating citations, terminal logs and test results per task. A GPT-5 system-card addendum published the same day describes specialized safety training for harmful tasks and prompt injection alongside product-level mitigations: agent sandboxing and configurable network access. OpenAI states plainly that Codex code review should be an additional reviewer, not a replacement for human review.

WHY IT MATTERS

A coding model that can spend anywhere from seconds to seven hours on one task moves the cost question from tokens to wall-clock and compute scheduling, so budget per-task timeouts and concurrency, not just per-call price. The real decision surface is the harness: sandboxing, network access and MCP permissions are the knobs you configure, and the same GPT-5-Codex shipped with agent sandboxing is the one whose code-review output you are being invited to trust in CI — add it as a second reviewer with logged evidence, not as a gate.